Internal Linking Audit: Find Orphaned and Underlinked Pages
Find orphan candidates and contextually underlinked pages with a sitemap-to-crawl check, a real before-and-after link example, and an audit worksheet.

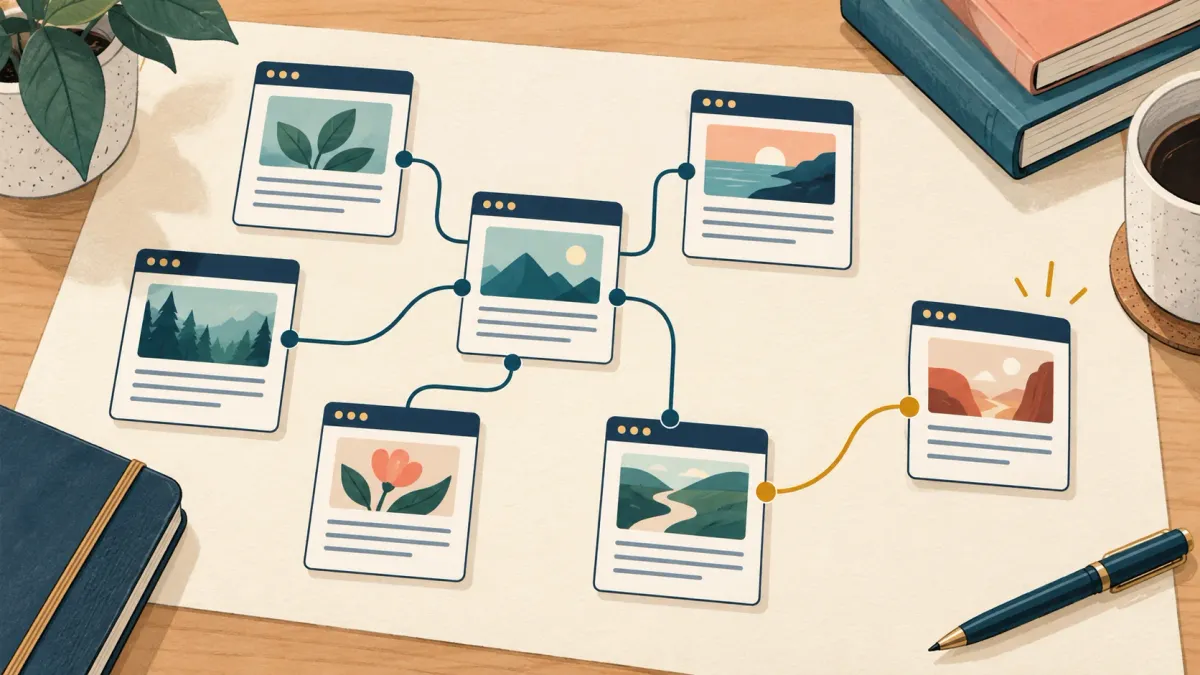
An internal linking audit starts by comparing the pages you want people to find with the links a visitor or crawler can actually follow. A URL with no discovered incoming internal link is an orphan candidate. A page reached through navigation or automatic related-post cards but never linked from a relevant explanation may be underlinked in context. These are different problems and call for different fixes.
You do not need to add five links to every page. Google says every page you care about should have a link from at least one other page on your site, and that there is no magical ideal number of links. The useful question is: can a reader reach this page at the moment it helps them complete their task?
First, separate three kinds of evidence
- Your page inventory: the canonical URLs you intend to maintain, usually from your XML sitemap, CMS export, or both. A sitemap is a discovery aid, not a promise that each URL will be crawled or indexed. See Google's sitemap overview.
- A link crawl: the URLs a crawler reaches from your homepage and other starting points, plus the source page, destination, and anchor for each internal link. Include navigation, pagination, category or tag paths, and rendered JavaScript links when the site relies on them.
- Search Console's Links report: a useful second view of links Google has found. It is a sample, not a complete or live list; URLs can be omitted or grouped by canonical, and links may remain after removal. Do not declare a page orphaned because it is absent from that report.
Our content-map guide helps decide which reader task a page should serve. This audit asks the next question: which existing pages should help the right reader reach it?
A practical audit in five steps
1. Build the target list
Export the URLs you want found. For a small site, a sitemap and a sheet are enough to start; a larger site may need a CMS export too. Record each URL's intended role: guide, category, service, product, tool, or support page. Check that each important target returns a useful page, is indexable when intended, and points to its preferred canonical URL. A redirect, duplicate, private page, or deliberate noindex is not a content orphan to “fix” with extra links.
2. Crawl paths from real entry points
Use a crawler that exports internal links, or manually inspect a small set of important pages. Start at the homepage, follow pagination and navigation, and include topic hubs and category pages. For each source → target link, note whether it appears in a menu, footer, related-content module, or the main content. Count distinct source URLs rather than counting the same source-target pair several times.
Check the actual link markup. Google can generally follow an <a href="/destination/"> link; a clickable element that only runs script is less reliable. Its link guidance also recommends concise, descriptive anchor text and a sentence that makes the destination useful. If your site builds links in JavaScript, inspect the rendered page rather than assuming source HTML and rendered HTML match.
3. Compare the inventory and crawl
A target in the inventory but missing from a homepage-based crawl is an orphan candidate. Verify the crawl's scope before changing the site: did it include pagination, a login wall, a relevant hub, and pages rendered with JavaScript? A URL may be discoverable through a sitemap, external link, or another path your crawl missed. Conversely, a page that appears in the crawl only because every post has a “Read more” card may still need a contextual route from a closely related page. Call it underlinked in context, not orphaned.
Search Console's Links report can help you find source URLs worth checking, but its sampled counts are not a substitute for your own current crawl. URL Inspection can tell you whether a specific target is indexed; indexing status alone does not tell you whether your site navigation is useful.
4. Choose one source because it helps the reader
Open a plausible source page and ask where the reader would naturally want the next answer. A guide about collecting and grouping queries can lead to a deeper decision about whether two queries belong on one page. A product category can lead to a fit guide. Put the link near that decision, use an anchor that describes the next page, and point at the final canonical URL. Avoid sitewide link blocks or repeated exact-match anchors merely to raise a count.
5. Verify the change and review later
After saving, check that the link appears in the public rendered HTML as an <a href>, that its destination returns the intended page, and that the source and target canonicals remain correct. Re-run the same bounded crawl and record what changed. If you later evaluate Search results, compare the target's non-branded clicks and relevant queries over completed periods alongside position and impressions. A link repair can improve navigation and discovery without producing a measurable ranking jump.
Worked example from this site's public pages
On 16 October 2026, before this article was published, a bounded audit compared the 15 canonical URLs in The SEO Station's public posts and pages sitemaps with links in their rendered pages. That bounded sample included the homepage, but did not crawl tag or author archives or paginated listing pages. The search-intent mapping guide was already reachable through the site's related-post cards. It was not an orphan.
The audit did show that none of the sampled article bodies linked to it. The older Search Console content-map guide discusses how to group query wording and explicitly says that a cluster is a hypothesis. That is where a reader may need the deeper one-page-or-two test. I added one sentence in that section with the anchor search-intent mapping test.
Before: zero distinct contextual article-body sources for the intent guide in this sample.
After: one contextual source, the content-map guide. Its count of source pages with any link did not rise, because the source already had a theme-generated related-post link. The new link makes the next step visible at the relevant moment. These are public link observations, not a traffic or ranking result.
Audit scope matters. If we had checked only Search Console's sampled Links report or only the homepage, we might have described this page incorrectly. If a real audit finds a zero-link target, check its full site paths before calling it orphaned or publishing a sitewide navigation change.
Copy this audit note for each candidate
Target URL and reader task: …
Should this page be indexable? Canonical URL: …
Inventory source and crawl date: …
Reachable path from an entry page: …
Distinct incoming sources: navigation / related cards / main content …
Candidate source and reader reason: …
Proposed sentence, anchor, and final destination: …
Live check: source link present / target HTTP result / canonical …
Review date and evidence: …
Start with five important targets, not every URL on a large site. Fix a broken or missing path when a relevant source exists; leave a page alone when another path already serves readers well. When your inventory suggests a new page rather than a link repair, use the intent-mapping test before creating a near duplicate. The result should be a site that is easier to navigate, with a link record you can verify again later.