Why a Page Is Not Indexed: A Search Console Decision Tree
Use a Search Console decision tree to separate expected exclusions from important pages that need investigation. Includes a public redirect example and triage worksheet.

“Not indexed” is a status, not a diagnosis. First decide whether this exact URL should appear in Google at all. A redirected, duplicate, intentionally blocked, or removed URL may be behaving correctly. If an important canonical page is missing, inspect that URL, compare Google's last crawl with the live page, and choose one action that matches the evidence.
This is a page-level decision guide for people who already know where to find Search Console. If you are setting it up, start with our five reports to check first. If crawling, indexing, and ranking still blur together, read the search-engine fundamentals guide before using the tree below.
Start with one URL you actually care about
Open Indexing → Pages to see patterns, then inspect an important URL directly in the search bar at the top of Search Console. Google's Page indexing report help says that non-indexed pages are not necessarily errors, and that URL Inspection is the tool for the status of a specific page. The aggregate report and its example list can lag; an old group count is not a fresh verdict on every article.
Write down the intended canonical URL before touching settings. Ask: is this the page you want visitors to find, or is it an alternate address, tracking variant, redirect, internal-search result, or retired page? If it should not be a separate search result, inspect the destination or canonical page instead. Google says the aim is to index the canonical versions of important pages, not every URL it has discovered.
A decision tree for a page that is not indexed
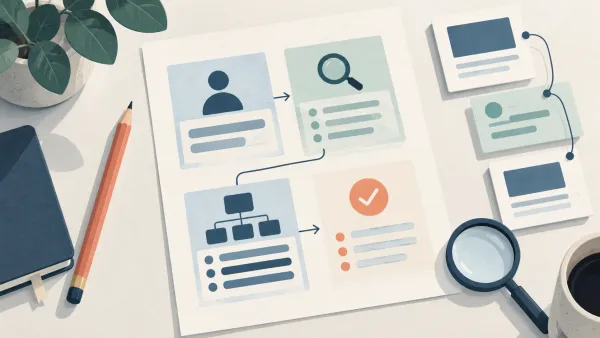
- Should this exact URL be indexed? If no, check that its redirect, canonical, noindex, or removal behavior is intentional and that users reach the right destination. Record “expected” and stop trying to index the alternate. If yes, continue.
- Does Search Console know it? If URL Inspection says the URL is unknown, confirm it is linked from a relevant, crawlable page or listed in the correct sitemap. Check that the URL is public and returns the page you intended. Discovery can take time; a sitemap helps Google find URLs but does not guarantee indexing.
- Has Google crawled it? “Discovered – currently not indexed” means Google knows the URL but has not crawled it yet. Inspect the live page, internal path, sitemap, server availability, and whether the URL is genuinely important. Do not diagnose its content quality from a page Google has not fetched. Google's documentation notes that it may reschedule a crawl; the reason label alone does not tell you what to change on your site.
- Was it crawled but left out? “Crawled – currently not indexed” means Google fetched it but has not indexed it. Compare the last crawl date and the crawled version with today's page. Check for a weak or overlapping page purpose, an unintended canonical, a soft 404, or content Google could not see. The label does not prove one particular defect. Google says the URL may be indexed later and there is no need to resubmit it just because of this status.
- Did the fetch or indexing controls fail? For a 5xx or access error, check server responses and logs, then test the current page; a successful live test does not erase an earlier transient failure. For an accidental noindex, remove the directive and allow Googlebot to crawl the page. For a robots.txt block, decide whether crawling should be allowed. Do not use robots.txt as a noindex switch: Googlebot needs access to see a page's noindex rule.
- Did Google choose another canonical? In the indexed URL Inspection details, compare the user-declared and Google-selected canonicals, then read both pages. If the other URL is the version you want, the exclusion may be fine. If not, repair conflicting redirects, canonicals, internal links, or near-duplicate content where the evidence points. The live test cannot predict Google's eventual canonical selection.
The first branch prevents wasted work; the later branches narrow a genuine problem. Google's URL Inspection documentation separates the indexed version from a live test. “URL is available to Google” means the live page can probably be crawled and parsed, not that it is indexed or guaranteed to become indexed. The live test follows redirects without clearly reporting that it did so, so inspect the original URL and its destination separately when redirects matter.
What common Page indexing reasons call for
- Page with redirect: Usually expected for an alternate URL. Verify the redirect reaches the right canonical page and inspect the destination's own status. A redirect error is different: a loop, broken chain, or bad target needs repair.
- Alternate or duplicate: Check the Google-selected canonical. Google does not need to index every copy. If the chosen page is wrong, compare the pages and signals rather than adding a canonical tag blindly; Google's canonical guidance describes redirects and rel=canonical as strong signals, not commands.
- Excluded by noindex: Expected for a page you intentionally kept out of Search. If it is an important public page, remove the accidental directive and confirm the crawler can access it. A robots.txt block can prevent Google from seeing noindex; Google's noindex guidance explains the interaction.
- 404 or soft 404: A genuinely removed page without a replacement can remain a 404. Fix important internal links or sitemap entries pointing to it. If a useful replacement exists, plan an appropriate redirect. A soft 404 needs a content and response check rather than a cosmetic title change.
- Discovered or crawled, currently not indexed: Use the corresponding branch above. Neither label gives you permission to declare “low quality” from one row, and repeatedly requesting indexing is not a substitute for diagnosing the important URL.
A public example: the alternate homepage that should redirect
On 23 October 2026, a public HTTP check of https://www.theseostation.com/ returned 308 Permanent Redirect to https://theseostation.com/. The clean destination returned a normal page with a self-referencing canonical. The response headers from that check are a public, reproducible observation; they are not a screenshot or disclosure of this site's private Search Console report.
If a comparable www alternate appeared under “Page with redirect,” the right question would be whether its destination is the intended homepage and whether that clean URL is indexed. Asking Google to index the redirecting www address separately would work against the site's URL choice. A different result—a redirect loop or a destination that fails—would call for a fix. One reason label does not settle the case without the URL's role and response.
Copy this one-URL triage record
Use one row per important URL. The record makes the next check explicit and stops a large exclusion count from becoming a vague sitewide “fix.”
- URL inspected and date: The full URL, Search Console property, and when you checked it.
- Should it be indexed? Yes, no, or undecided; name the intended canonical and why this page matters.
- Indexed view: Status, report reason, last crawl, page fetch, indexing allowed, and Google-selected canonical when available.
- Live evidence: Current HTTP result, redirect target, robots/noindex state, visible content, sitemap entry, and relevant internal link path.
- Mismatch: What changed since Google's last crawl? Which observation supports a real problem rather than an expected exclusion?
- One action and owner: Keep as intended, fix a specific control/response/link/content issue, wait for a normal crawl, or escalate a server problem.
- Recheck date and outcome: Reinspect the same URL after Google has had time to crawl. Record the actual indexed result, not just whether a request was submitted.
When an important new or materially updated page is live, accessible, and eligible, you may request indexing once in URL Inspection. Google says a request only queues a crawl and does not guarantee inclusion; repeating it will not make the page move faster. For many pages, maintain an accurate sitemap and useful internal links. Our internal-linking audit can help verify a path from existing guides. If you are commissioning a distinct new guide after diagnosis, use the content-brief worksheet to define its task and evidence before publishing another URL.